The Frontier AI Inference Cloud
Inference performance drives profitability.
Deploy frontier open-weight and custom AI models with unmatched efficiency—maximizing tokens and margins.
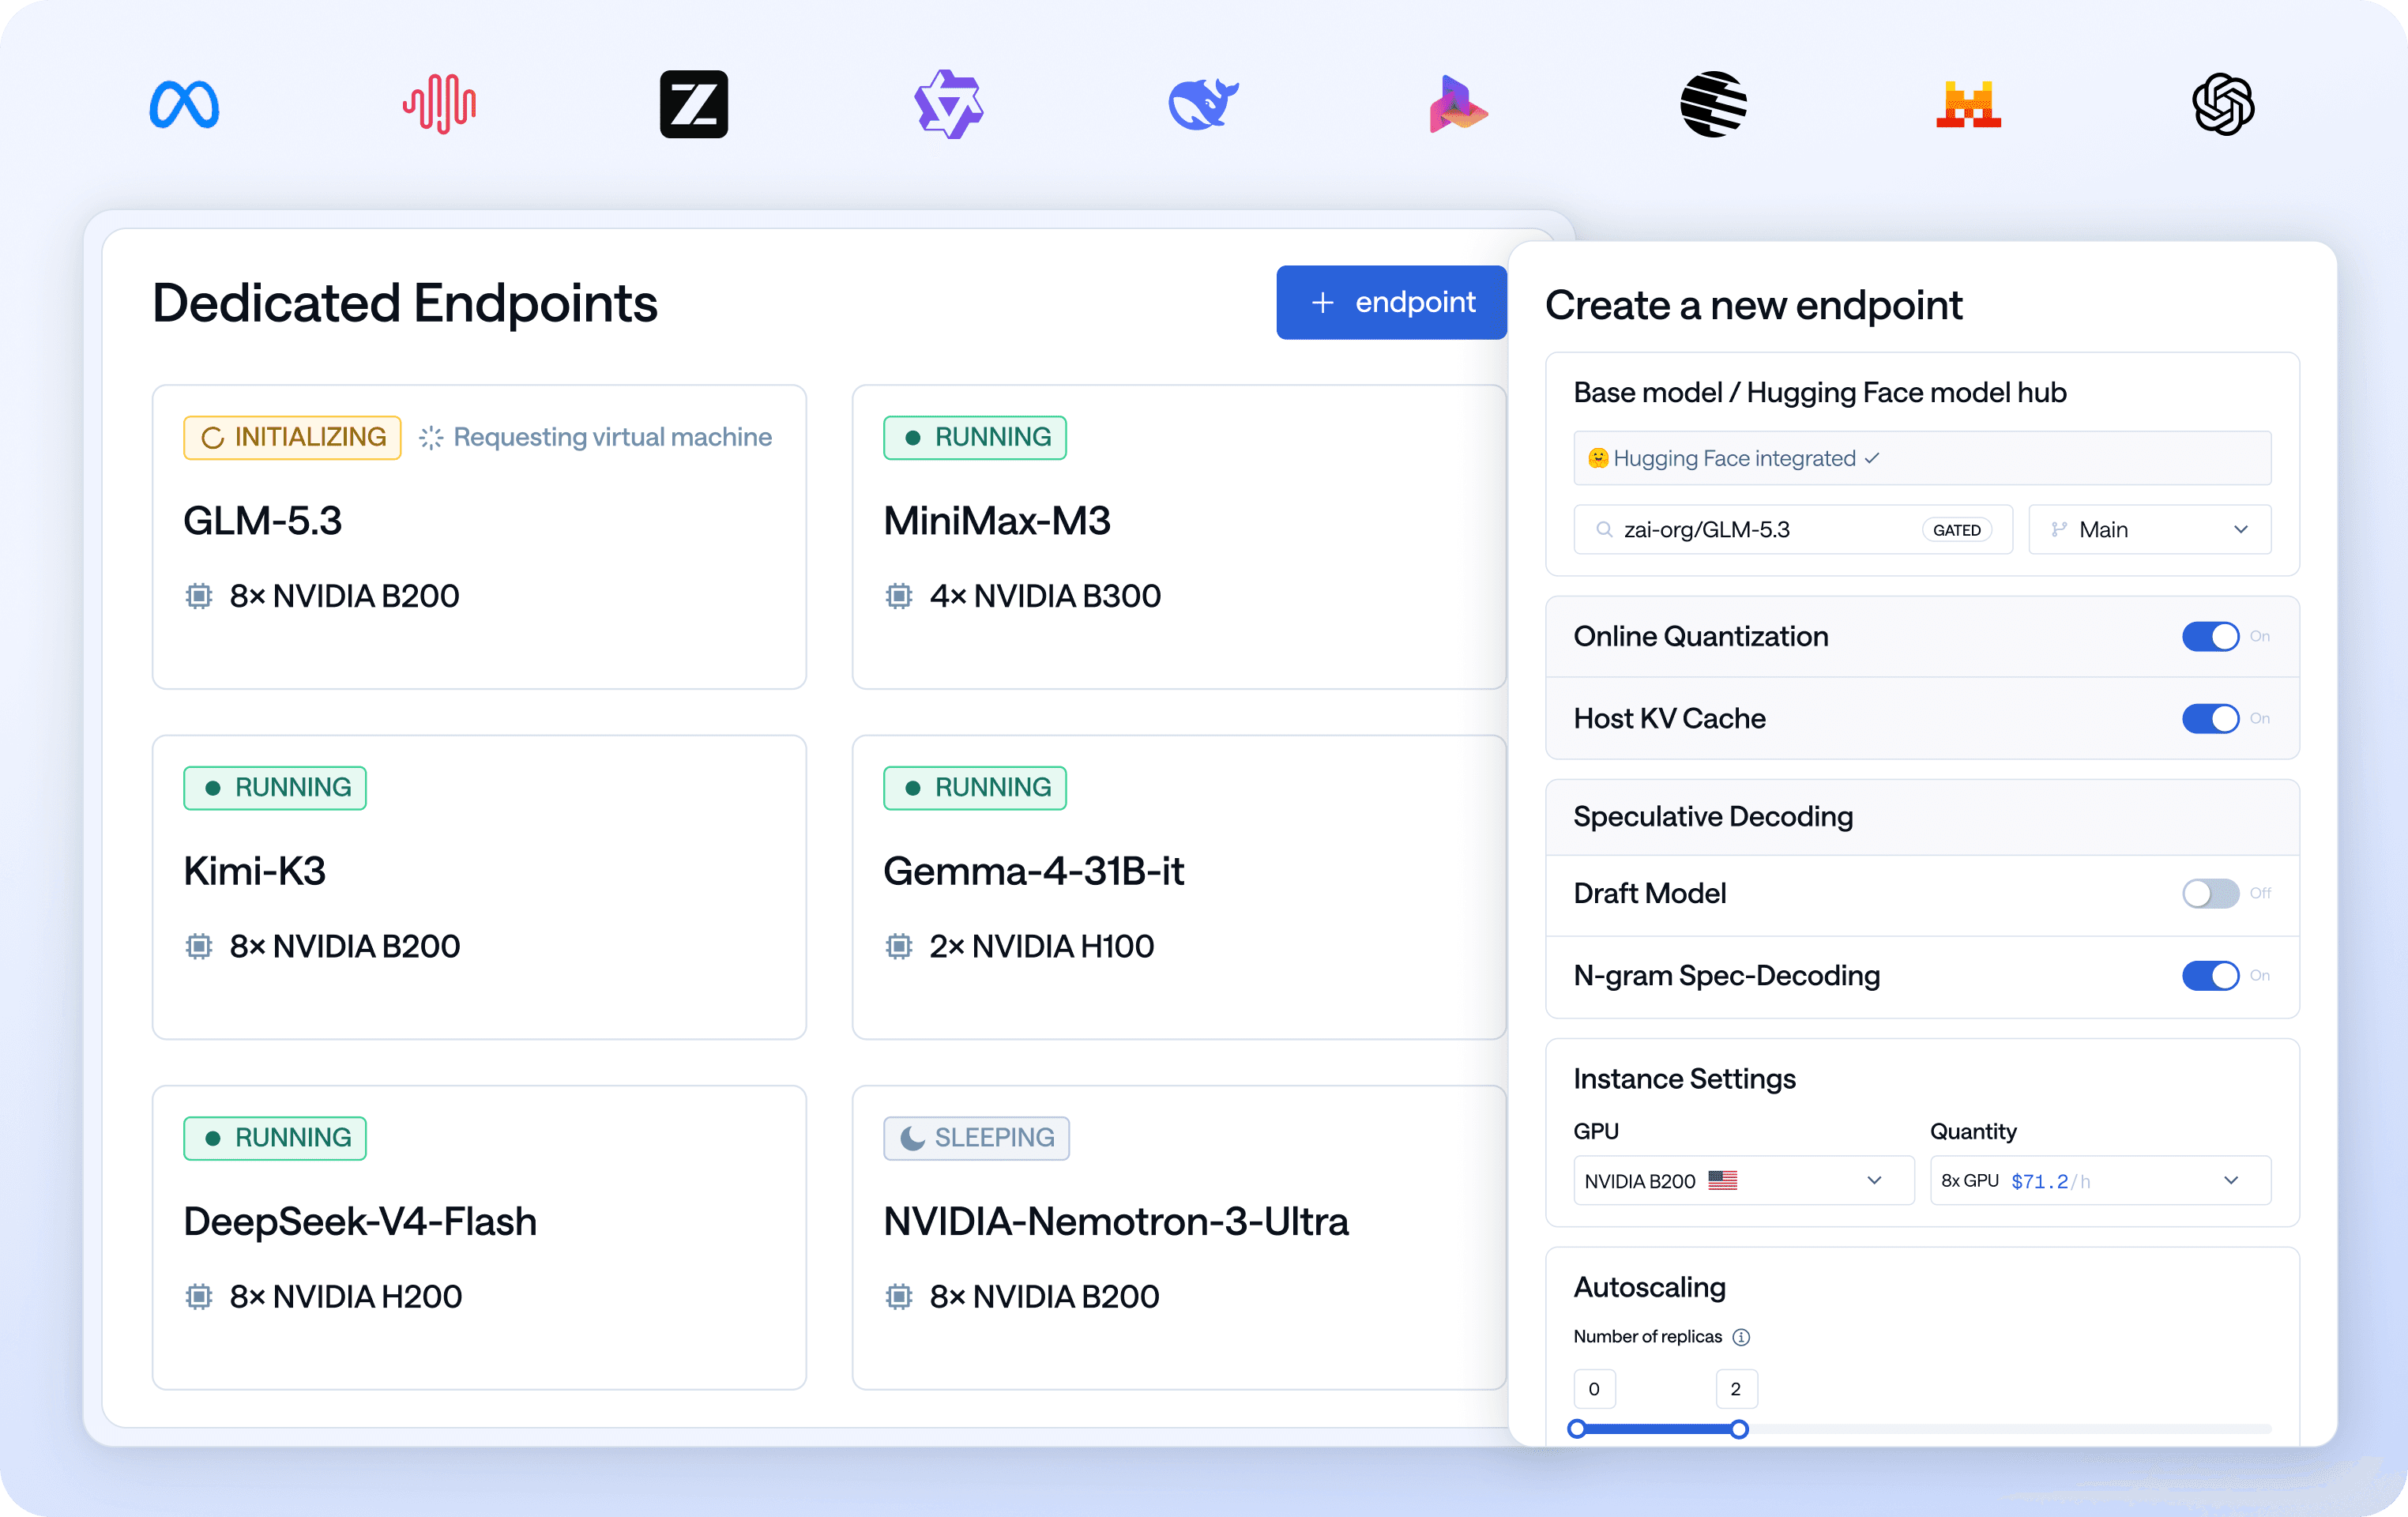
The fastest inference platform
Turn latency into your competitive advantage. Our purpose-built stack delivers 2×+ faster inference, combining model-level breakthroughs — custom GPU kernels, smart caching, continuous batching, speculative decoding, and parallel inference — with infrastructure-level optimizations like advanced caching and multi-cloud scaling. The result is unmatched throughput, ultra-low latency, and cost efficiency that scale seamlessly across abundant GPU resources.


Guaranteed reliability, globally delivered
FriendliAI delivers 99.99% uptime SLAs with geo-distributed infrastructure and enterprise-grade fault tolerance. Your AI stays online and responsive through unpredictable traffic spikes and across global regions — scaling reliably with your business growth and backed by fleets of GPUs across regions. With built-in monitoring and compliance-ready architecture, you can trust FriendliAI to keep mission-critical workloads running wherever your users are.
620,000 models, ready to go
Instantly deploy any of 620,000 Hugging Face models — from language to audio to vision — with a single click. No setup or manual optimization required: FriendliAI takes care of deployment, scaling, and performance tuning for you. Need something custom? Bring your own fine-tuned or proprietary models, and we’ll help you deploy them just as seamlessly — with enterprise-grade reliability and control.
How teams scale with FriendliAI
Learn how leading companies achieve unmatched performance, scalability, and reliability with FriendliAI
FriendliAI was consistently 7 times faster and had a significantly lower error rate.

Our custom model API went live in about a day with enterprise-grade monitoring built in.

Rock-solid reliability with ultra-low tail latency.

Scale to trillions of tokens with 50% fewer GPUs, thanks to FriendliAI.

Fluctuating traffic is no longer a concern because autoscaling just works.

FriendliAI was consistently 7 times faster and had a significantly lower error rate.
Our custom model API went live in about a day with enterprise-grade monitoring built in.
Rock-solid reliability with ultra-low tail latency.
Scale to trillions of tokens with 50% fewer GPUs, thanks to FriendliAI.
Fluctuating traffic is no longer a concern because autoscaling just works.
Latest from FriendliAI
FriendliAI and Ollama Join Forces to Accelerate Open Model Adoption Among Korean Enterprises
FriendliAI and Ollama Join Forces to Accelerate Open Model Adoption Among Korean Enterprises
Meet FriendliLink: One Command to Connect Open-Weight Models to Your Coding Agents
When Open Models Beat Astra and Fable and When They Don’t?
GLM-5.3 and GLM-5.3-Flash Lower Cost per Task in Different Ways
One Model, Many Providers: How to Get Provider Routing Right

GLM-5.3 vs. Kimi K3: What Coding Agent Benchmarks Don’t Tell You

NVIDIA Nemotron 3.5 Lightning on FriendliAI: Built for Agent Harnesses, Ready for Production, Available Day-0

Frontier Retrieval Accuracy, Practical Deployment: NVIDIA Nemotron 3 Embed on FriendliAI

Structured Output Requires More Than Guided Generation

How Kilo Code and FriendliAI Bring Open Source AI Coding Agents to Production with NVIDIA Nemotron

GLM-5.2, Day-0 on FriendliAI Model APIs: The Strongest Open Model for Long-Horizon Agentic and Coding Tasks

At What Scale Do Dedicated Endpoints Make Sense?

Run NVIDIA's Most Powerful Open Reasoning Model on Day 0 — Nemotron 3 Ultra on FriendliAI

One Benchmark Is Not Enough to Choose Your Inference Provider

Kimi K2.6 Meets FriendliAI: Frontier Agentic AI, Deployed in One Click

Accelerating Inference on Friendli Dedicated Endpoints with Draft-Model Speculative Decoding

What's So Special About DeepSeek V4? Find Out On FriendliAI

FriendliAI Expands to San Francisco to Scale Frontier AI Inference for Open-Weight and Custom Models
FriendliAI Expands to San Francisco to Scale Frontier AI Inference for Open-Weight and Custom Models
FriendliAI and Ollama Join Forces to Accelerate Open Model Adoption Among Korean Enterprises
FriendliAI and Ollama Join Forces to Accelerate Open Model Adoption Among Korean Enterprises
Meet FriendliLink: One Command to Connect Open-Weight Models to Your Coding Agents
When Open Models Beat Astra and Fable and When They Don’t?
GLM-5.3 and GLM-5.3-Flash Lower Cost per Task in Different Ways
One Model, Many Providers: How to Get Provider Routing Right
GLM-5.3 vs. Kimi K3: What Coding Agent Benchmarks Don’t Tell You
NVIDIA Nemotron 3.5 Lightning on FriendliAI: Built for Agent Harnesses, Ready for Production, Available Day-0
Frontier Retrieval Accuracy, Practical Deployment: NVIDIA Nemotron 3 Embed on FriendliAI
Structured Output Requires More Than Guided Generation
How Kilo Code and FriendliAI Bring Open Source AI Coding Agents to Production with NVIDIA Nemotron
GLM-5.2, Day-0 on FriendliAI Model APIs: The Strongest Open Model for Long-Horizon Agentic and Coding Tasks
At What Scale Do Dedicated Endpoints Make Sense?
Run NVIDIA's Most Powerful Open Reasoning Model on Day 0 — Nemotron 3 Ultra on FriendliAI
One Benchmark Is Not Enough to Choose Your Inference Provider
Kimi K2.6 Meets FriendliAI: Frontier Agentic AI, Deployed in One Click
Accelerating Inference on Friendli Dedicated Endpoints with Draft-Model Speculative Decoding
What's So Special About DeepSeek V4? Find Out On FriendliAI
FriendliAI Expands to San Francisco to Scale Frontier AI Inference for Open-Weight and Custom Models
FriendliAI Expands to San Francisco to Scale Frontier AI Inference for Open-Weight and Custom Models